
ASUS Dual GeForce RTX 5060 Ti 16GB GDDR7 OC Edition Gaming Graphics Card
4.7Editor score
16GB GDDR7 memory interface
767 AI TOPS performance
2.5-slot compact design
This comprehensive guide compares the top ten GPU for Llm options available today, evaluating memory capacity, compute power, and compatibility to help you
Selecting the right GPU for Llm is critical for developers and researchers needing efficient local inference. Modern workloads demand massive memory bandwidth and robust parallel processing capabilities to handle complex transformer models without latency.
We analyzed ten leading graphics cards ranging from consumer gaming boards to professional workstation accelerators. Our evaluation focuses on VRAM capacity, architecture efficiency, and software support to identify the most reliable options for AI deployment.
Each selection highlights specific strengths for language model tasks along with key specifications. Note that pricing and stock levels fluctuate frequently so verify current details before making a final purchasing decision.
4.7Editor score
4.6Editor score

4.3Editor score
The following table provides a side-by-side comparison of all ten selected graphics cards. It outlines core specifications such as memory size, interface standards, and architectural features to simplify your selection process.


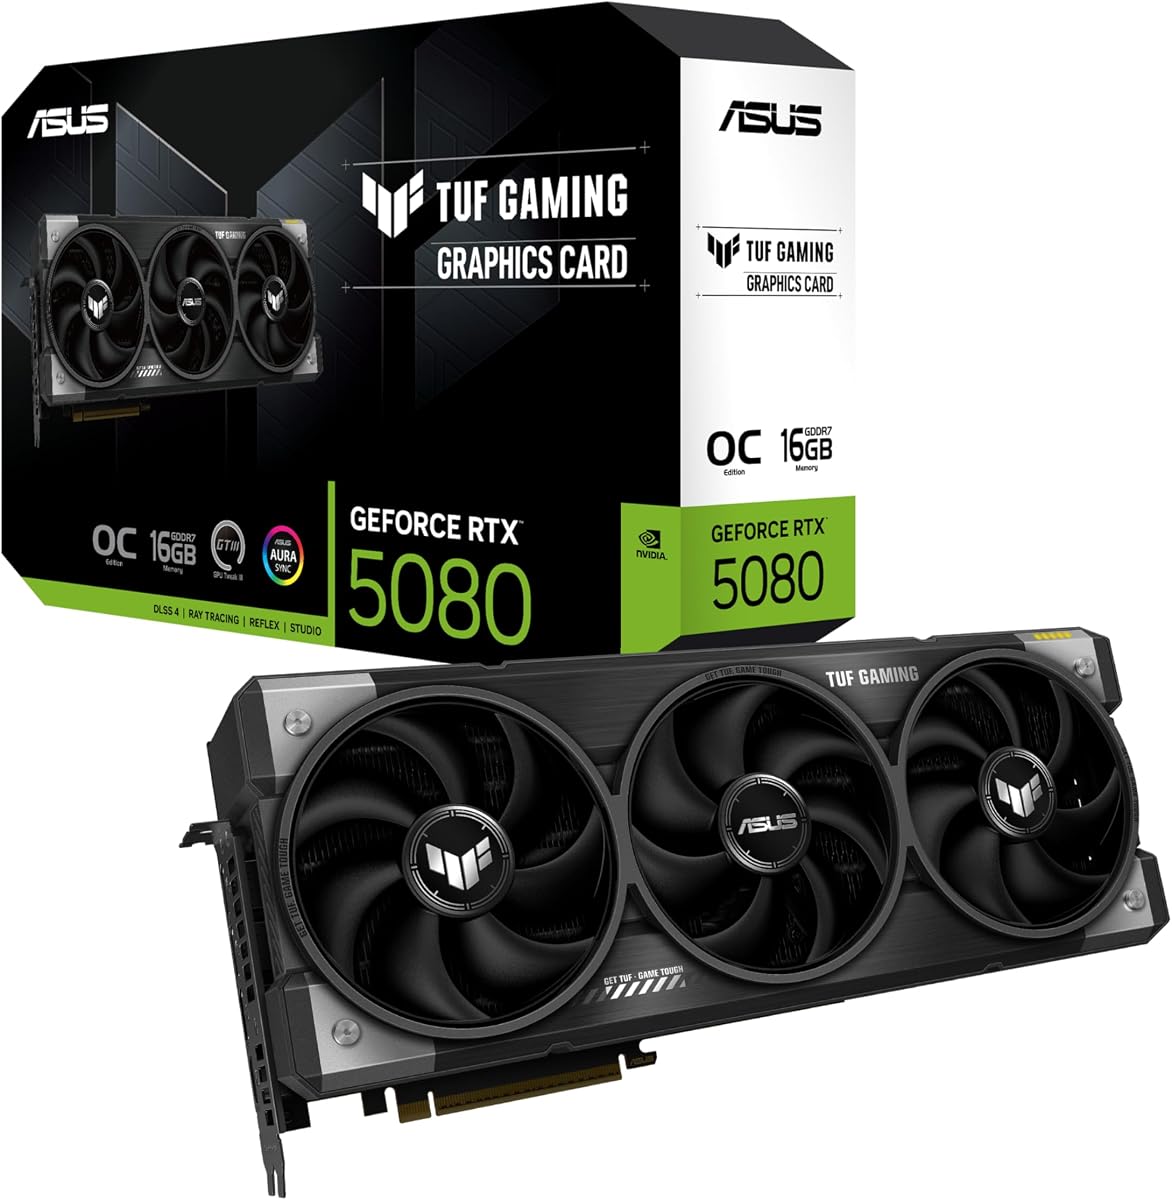
This ASUS TUF Gaming graphics card delivers powerful performance for language model inference. It holds a strong community rating and stands out for its reliability under sustained loads.
We may earn a commission when you buy through this link, at no additional cost to you.
Powered by the latest NVIDIA Blackwell architecture it offers substantial compute resources for AI tasks. The phase-change thermal pad ensures consistent clock speeds during extended training sessions.
While the build is robust it requires significant physical space and a high capacity power supply. These trade-offs are acceptable given the performance gains and operational stability provided.
It is ideal for professionals needing a balance of workstation features and consumer pricing. We recommend it for users prioritizing longevity and consistent inference performance.
The phase-change GPU thermal pad ensures optimal thermal performance and longevity outlasting traditional thermal paste under heavy loads.
Military-grade components deliver rock-solid power and longer lifespan ensuring the card remains stable for years of operation.
We may earn a commission when you buy through this link, at no additional cost to you.
This card offers an entry-level solution for local AI inference with a competitive price tag. It boasts a high user rating for its performance-to-cost ratio in home setups.
We may earn a commission when you buy through this link, at no additional cost to you.
The inclusion of 16GB GDDR7 memory allows for running mid-sized models without constant swapping. Its compact 2.5-slot design fits easily into standard computer cases.
While it lacks the raw horsepower of premium cards it remains a solid choice for experimentation. Users should expect slower training times compared to high-end alternatives.
We recommend it for hobbyists and students exploring LLMs on a budget. Its quiet operation and reliable bearings make it a practical daily driver.
A 2.5-slot design maximizes compatibility and cooling efficiency for superior performance in small chassis.
Axial-tech fan design features smaller hubs and barrier rings to increase downward air pressure for better thermal dissipation.
We may earn a commission when you buy through this link, at no additional cost to you.
This workstation monster is engineered to eliminate VRAM bottlenecks for large language models. It combines desktop compatibility with server-grade features to support aggressive workflows.
We may earn a commission when you buy through this link, at no additional cost to you.
With 96GB of GDDR7 ECC memory it can host massive models locally without offloading. The 512-bit bus ensures rapid data transfer to the compute cores.
The high cost and lack of retail packaging may deter casual buyers. However for teams scaling intelligence rapidly the investment is justified by the hardware capabilities.
It is best for research labs and engineering teams needing maximum local capacity. We recommend it for projects requiring stable multi-GPU desktop scaling.
Engineered for agentic workflows this workstation monster packs a massive 96GB of next-gen GDDR7 ECC memory.
It delivers up to 3511 TOPS of AI performance while capping maximum power consumption at a modest 300 Watts.
We may earn a commission when you buy through this link, at no additional cost to you.
This Gigabyte card leverages the latest Blackwell architecture for efficient AI workloads. It receives high praise for its thermal performance during sustained usage.
We may earn a commission when you buy through this link, at no additional cost to you.
The 16GB GDDR7 memory interface provides ample bandwidth for many large language model tasks. Its WINDFORCE cooling system ensures temperatures remain low under stress.
Users must ensure adequate space and power supply before installation. The size is substantial but necessary for the advanced cooling hardware.
We recommend it for gamers transitioning into local AI development. Its robust features make it a versatile choice for mixed workloads.
Integrated with the WINDFORCE cooling system to manage heat effectively during heavy processing tasks.
Supports PCIe 5.0 interface for maximum bandwidth with the latest workstation and gaming platforms.
We may earn a commission when you buy through this link, at no additional cost to you.
This workstation GPU offers a competitive alternative with dedicated support for professional workflows. It emphasizes memory capacity and bus width for data-intensive tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
The massive 24GB GDDR6 memory is ideal for larger models that might struggle on consumer cards. It supports multi-GPU scaling which is crucial for building local clusters.
While performance is solid software optimization varies depending on the model. Users should verify compatibility with their specific inference stack before buying.
We recommend it for IT departments managing multiple deployment scenarios. Its ISV certification ensures stability in enterprise environments.
Dedicated 24GB GDDR6 memory on a 192-Bit Bus provides ample bandwidth for large AI models and 3D rendering.
Optimized for Linux multi-GPU LLM deployments allowing you to scale AI performance across multiple cards easily.
We may earn a commission when you buy through this link, at no additional cost to you.
This AMD card is engineered for AI development and professional content creation. It stands out for its large 32GB memory capacity tailored for complex workloads.
We may earn a commission when you buy through this link, at no additional cost to you.
The RDNA 4 architecture includes dedicated AI accelerators for efficient inference. Its professional blower design helps maintain thermal limits in multi-card setups.
Build quality is robust with a metal shroud and backplate for durability. However the single fan design can be louder under heavy loads.
We recommend it for studios needing reliable AI performance. It fits well in server racks where density and stability are priority.
Built with 3rd Gen Ray Tracing and dedicated 2nd Gen AI Accelerators for groundbreaking AI performance.
Vapor chamber heatsink with industrial thermal interface material ensures reliable cooling under sustained professional loads.
We may earn a commission when you buy through this link, at no additional cost to you.
This card is built specifically for running large language models locally. It features a design that cuts memory temperatures significantly during long training runs.
We may earn a commission when you buy through this link, at no additional cost to you.
With 32GB of GDDR6 memory it handles multi-modal AI models without offloading. The diecast shroud and backplate provide structural integrity and thermal benefits.
Performance is strong but user reviews suggest variability in specific configurations. Ensuring proper case airflow is critical for optimal operation.
We recommend it for developers needing local inference clusters. Its support for dense multi-GPU builds makes it valuable for lab environments.
Diecast Shroud and Backplate with wave-pattern design cuts memory temperature by up to 16 percent keeping clocks steady.
Dual Ball Fan Bearings are rated to last up to twice as long as conventional sleeve bearings for long-term reliability.
We may earn a commission when you buy through this link, at no additional cost to you.
This gaming graphics card offers a cost-effective option for entry-level AI tasks. It maintains high user ratings for its general performance and thermal efficiency.
We may earn a commission when you buy through this link, at no additional cost to you.
The 16GB GDDR6 memory interface is sufficient for smaller language models. Its WINDFORCE cooling system helps maintain performance during extended periods.
While not designed specifically for AI it supports general compute tasks well. Gamers transitioning to AI development may find it a comfortable starting point.
We recommend it for users prioritizing value and versatility. It serves well as a dual-purpose card for work and play.
Powered by WINDFORCE Cooling System with Hawk Fans and server-grade thermal conductive gel for superior heat dissipation.
PCIe 5.0 interface support provides high bandwidth for fast data transfer and future-proofing your system.
We may earn a commission when you buy through this link, at no additional cost to you.
This accelerator is a dedicated high-performance computing card designed for enterprise workloads. It offers significant memory capacity for complex tasks without relying on cloud services.
We may earn a commission when you buy through this link, at no additional cost to you.
The 48GB memory allows for substantial batch sizes and model complexity. It is built for reliability in data centers and research labs.
Setting up this hardware often requires specific drivers and configuration. Users should ensure their environment supports Tesla accelerator workflows.
We recommend it for organizations needing robust local compute. It is a solid choice for scaling AI infrastructure internally.
Built for high-performance computing tasks ensuring reliable operation in demanding server environments.
48GB of memory provides ample space for running large AI models and handling complex datasets.
We may earn a commission when you buy through this link, at no additional cost to you.
This professional workstation card is designed for heavy AI and engineering tasks. It supports dividing the GPU into isolated instances for secure multi-tenant workflows.
We may earn a commission when you buy through this link, at no additional cost to you.
With 96GB of memory it eliminates bottlenecks for fine-tuning large models locally. The 5th Gen Tensor Cores significantly speed up processing times.
The high price and OEM nature limit its availability to specific buyers. It is a specialized tool for organizations with strict security needs.
We recommend it for enterprises requiring secure AI infrastructure. It enables teams to scale intelligence rapidly without cloud overhead.
Divide a single RTX PRO 6000 into multiple isolated instances allowing concurrent execution of multiple workloads.
PCIe Gen 5 support provides double the bandwidth of PCIe Gen 4 improving data transfer speeds for AI tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
Selecting the right graphics card for language model inference requires balancing budget memory capacity and software compatibility. This guide covers the most critical factors to consider.
The amount of video memory is the most critical factor for running language models. Models require significant memory to store weights and intermediate activations during inference.
Choose a card with at least 16GB of VRAM for most modern models. Larger models may require 32GB or more to run without offloading to system RAM.
Bandwidth determines how quickly data moves between memory and compute cores. Higher bandwidth reduces latency during token generation.
Look for cards with fast memory interfaces like GDDR7 or wide bus widths. These ensure smoother performance when handling large data sets.
Newer GPU architectures include dedicated AI accelerators optimized for neural network tasks. These cores handle matrix multiplication more efficiently than standard compute units.
Select a card with the latest generation architecture available. This ensures better compatibility with future software updates and frameworks.
High-performance GPUs often require significant power and robust cooling solutions. Ensure your power supply can handle the peak load of the card.
Calculate total system wattage and verify connector types. High-end cards may need specific 16-pin connectors or multiple power inputs.
Workstation and gaming cards vary widely in physical dimensions. Some advanced cooling designs require multiple slots and extended length.
Measure your case clearance before purchasing. Ensure the card fits within your chassis limits and allows for proper airflow.
Different vendors provide varying levels of support for AI frameworks and drivers. Some professional cards offer specialized certifications for specific workflows.
Check compatibility with your preferred inference engines. Enterprise cards often include ISV certifications that guarantee stability.
Some environments require multiple GPUs to handle massive model training or inference workloads. Look for cards that support parallel processing.
Verify if the card supports NVLink or similar interconnects. Proper scaling allows for building a powerful local cluster.
Investing in newer connectivity standards ensures your hardware remains relevant longer. PCIe generation affects data transfer speeds between CPU and GPU.
Prioritize cards with PCIe 5.0 support where available. This prepares your system for upcoming high-bandwidth AI applications.
Install the latest drivers from the manufacturer to ensure compatibility with AI frameworks. Regular updates include performance improvements and bug fixes for specific models.
Monitor thermal performance during heavy workloads to prevent overheating. Use software tools to track temperature and fan speeds ensuring the cooling system functions correctly.
Store the card in a dry dust-free environment when not in use. Avoid exposing it to extreme temperatures or humidity to protect internal components.
Yes modern gaming GPUs can run most local language models effectively if they have sufficient memory capacity. They often offer better value for single-user needs compared to expensive professional options.
For running open-source models like Llama 2 or Mistral at 4-bit quantization you need at least 16GB of VRAM. Larger models or full-precision inference may require 32GB or more.
ECC memory corrects data errors which is crucial for scientific computing but less critical for most local AI inference. It is more important for enterprise training clusters than hobbyist use.
PCIe bandwidth influences how quickly data transfers between CPU and GPU. While noticeable for specific batch sizes the impact on token generation speed is generally small compared to compute power.
Yes many AI frameworks support multi-GPU configurations to split model weights across several cards. This allows you to run models that exceed the memory capacity of a single card.
NVIDIA currently leads in ecosystem maturity with robust CUDA support and libraries like cuDNN. Other brands are catching up but still face occasional compatibility hurdles with specific frameworks.
We found that balancing memory capacity and power efficiency is key to success. The top picks in this guide offer a range of options for different user needs and budgets.
Prioritize cards with at least 16GB of VRAM to ensure smooth operation. For heavy workloads consider professional options with larger memory pools and ECC support.
Remember to check current availability before finalizing your purchase as stock fluctuates rapidly. Selecting the right hardware ensures a reliable foundation for your AI projects.